Standalone AP · h=5
Temporal GRU / current-force heuristic. 244 real trajectories, five tasks; 20,475 test windows in the reported study.
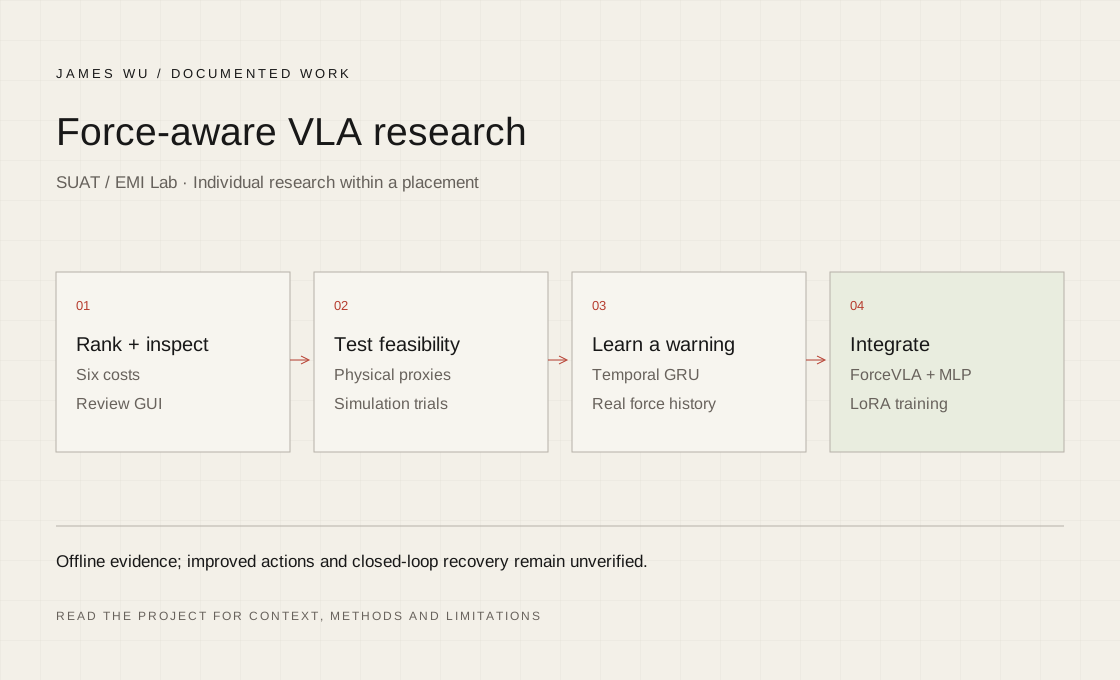
At SUAT’s EMI Lab, I explored how force and motion history could help a manipulation policy anticipate contact risk. I built a trajectory ranker and review GUI, tested simulation routes, then implemented and evaluated an auxiliary risk head during ForceVLA LoRA training.
 Inspect full-size image ↗
Open a chapter to follow the work and the choices made along the way.
I generated Franka trajectory candidates, calculated six cost components and trained a neural ranker. A GUI exposed grasp stability, stress/deformation, smoothness, acceleration, obstacle clearance and path length. This was relative ranking, not a calibrated safety score.
Inspect the supporting evidence ↓I explored simplified physical proxies, Isaac Lab/TacEx and MuJoCo replay. Contact fidelity, data-generation speed and available compute prevented a credible new dataset within the placement, so I moved to existing ForceVLA trajectories.
Inspect the supporting evidence ↓A standalone GRU used temporal history from 244 real inputForce trajectories across five tasks. At a five-step horizon, AP was 0.736 versus 0.571 for a current-force heuristic. The reported test set contained 20,475 windows.
Inspect the supporting evidence ↓I added an auxiliary MLP risk head during ForceVLA LoRA training. Limited offline subsets produced AUROC 0.759 at h=5 and 0.748 at h=15 against force-derived proxy labels. No robust action-loss improvement was established and no closed-loop rollout was conducted.
Inspect the supporting evidence ↓Offline experiments only, without closed-loop robot validation. The standalone GRU and integrated MLP are different models and evaluations; a reliable improvement in action prediction was not established.
Temporal GRU / current-force heuristic. 244 real trajectories, five tasks; 20,475 test windows in the reported study.
ForceVLA auxiliary MLP head on limited offline subsets with force-derived proxy labels.
The proxy warning signal was learnable. Safer stopping, retraction, recovery and improved task success have not been demonstrated.
Same reported pilot; 244 trajectories across five tasks. The integrated model is evaluated separately.
Research context, individual responsibilities and reasons for the simulation-to-ForceVLA pivot.
Later results and explicit limits; read alongside the interim report.
Standalone GRU / heuristic comparison; integration status on slide 2 predates the later review.
Related by practice, not just by category.
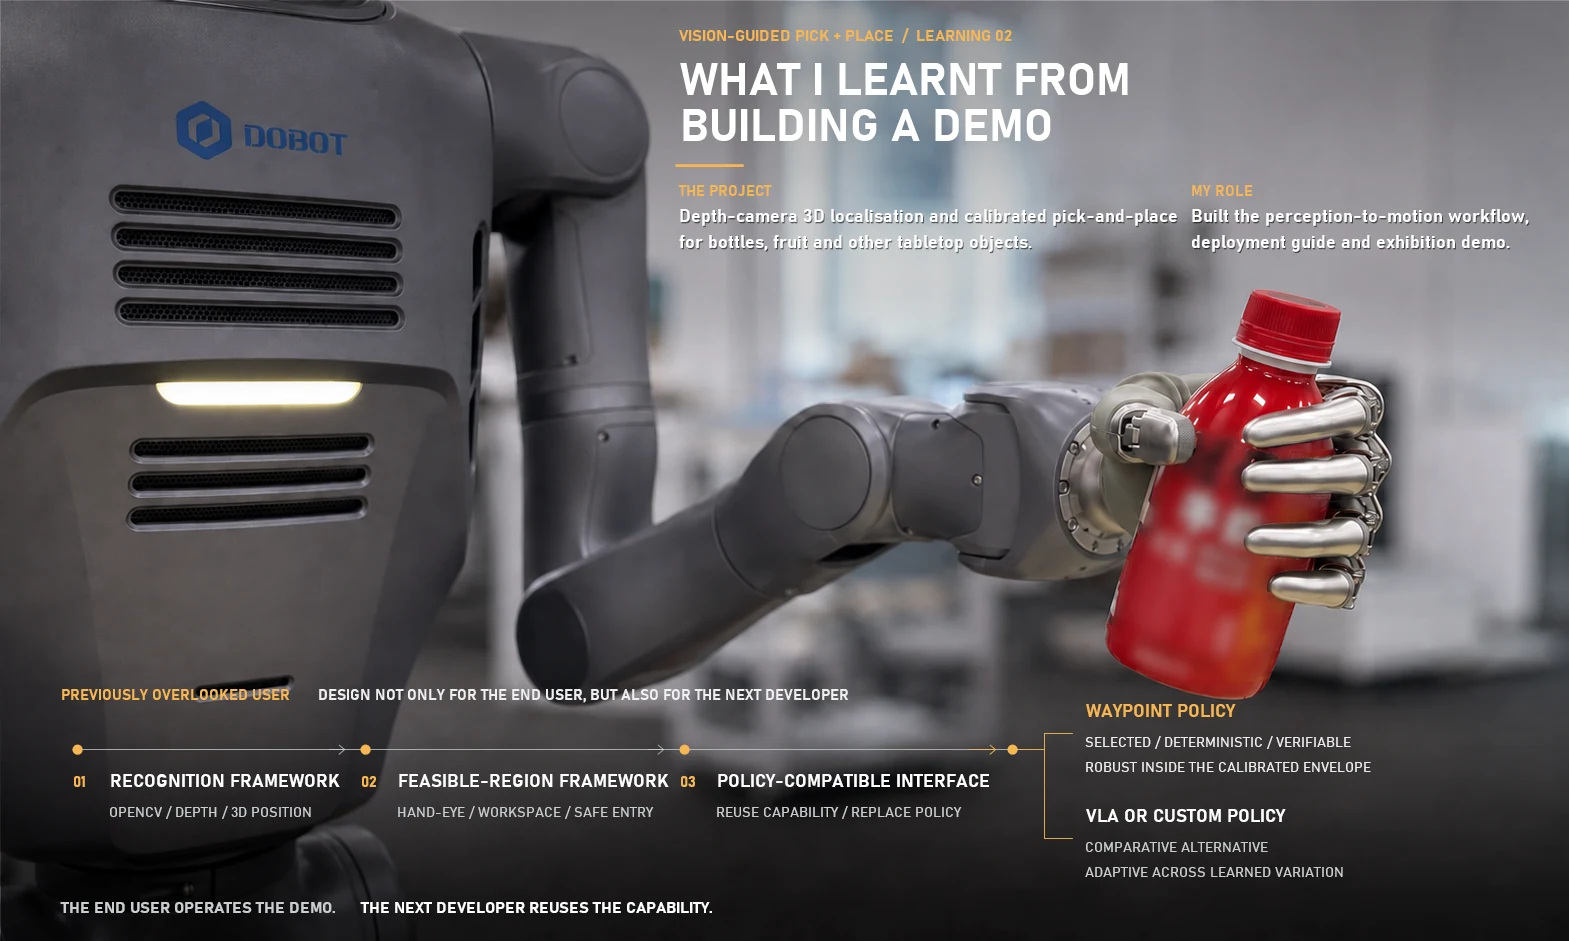
Hands-on experience connecting physical robots, perception, control and services through task demonstrations, teleoperation, navigation experiments and hardware work.
My partTechnical Support Engineer Intern · robot applications and testing
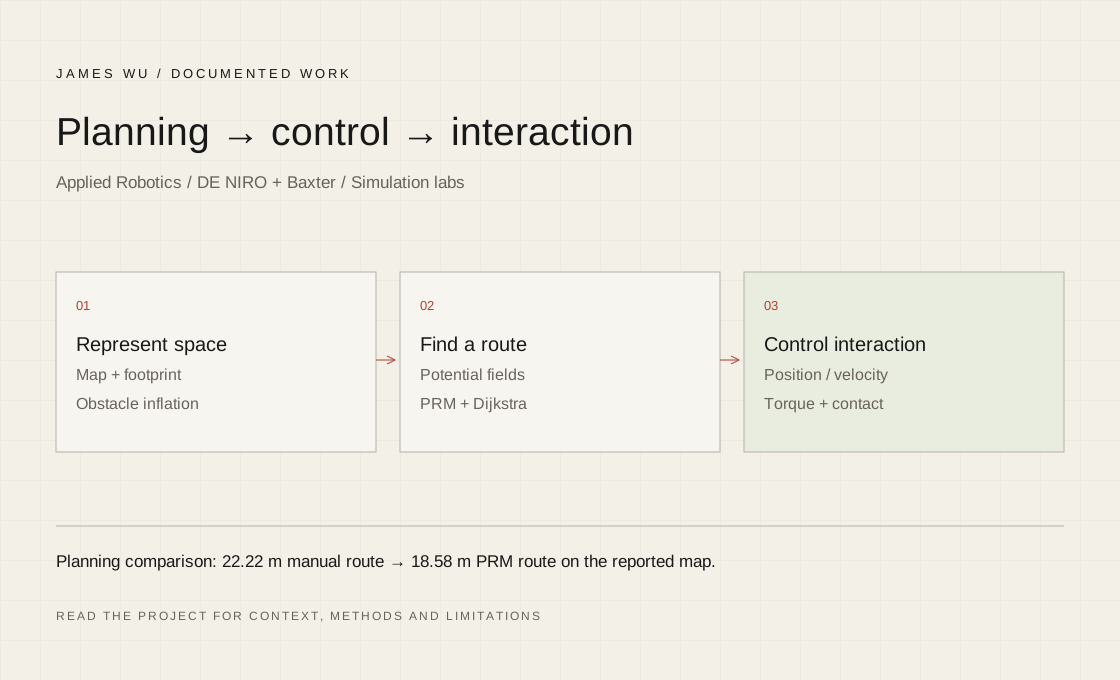
Two connected lab studies: compare planners on an indoor map, then use position, velocity and torque control for manipulation and interaction.
Independent projectIndependent lab implementation and analysis
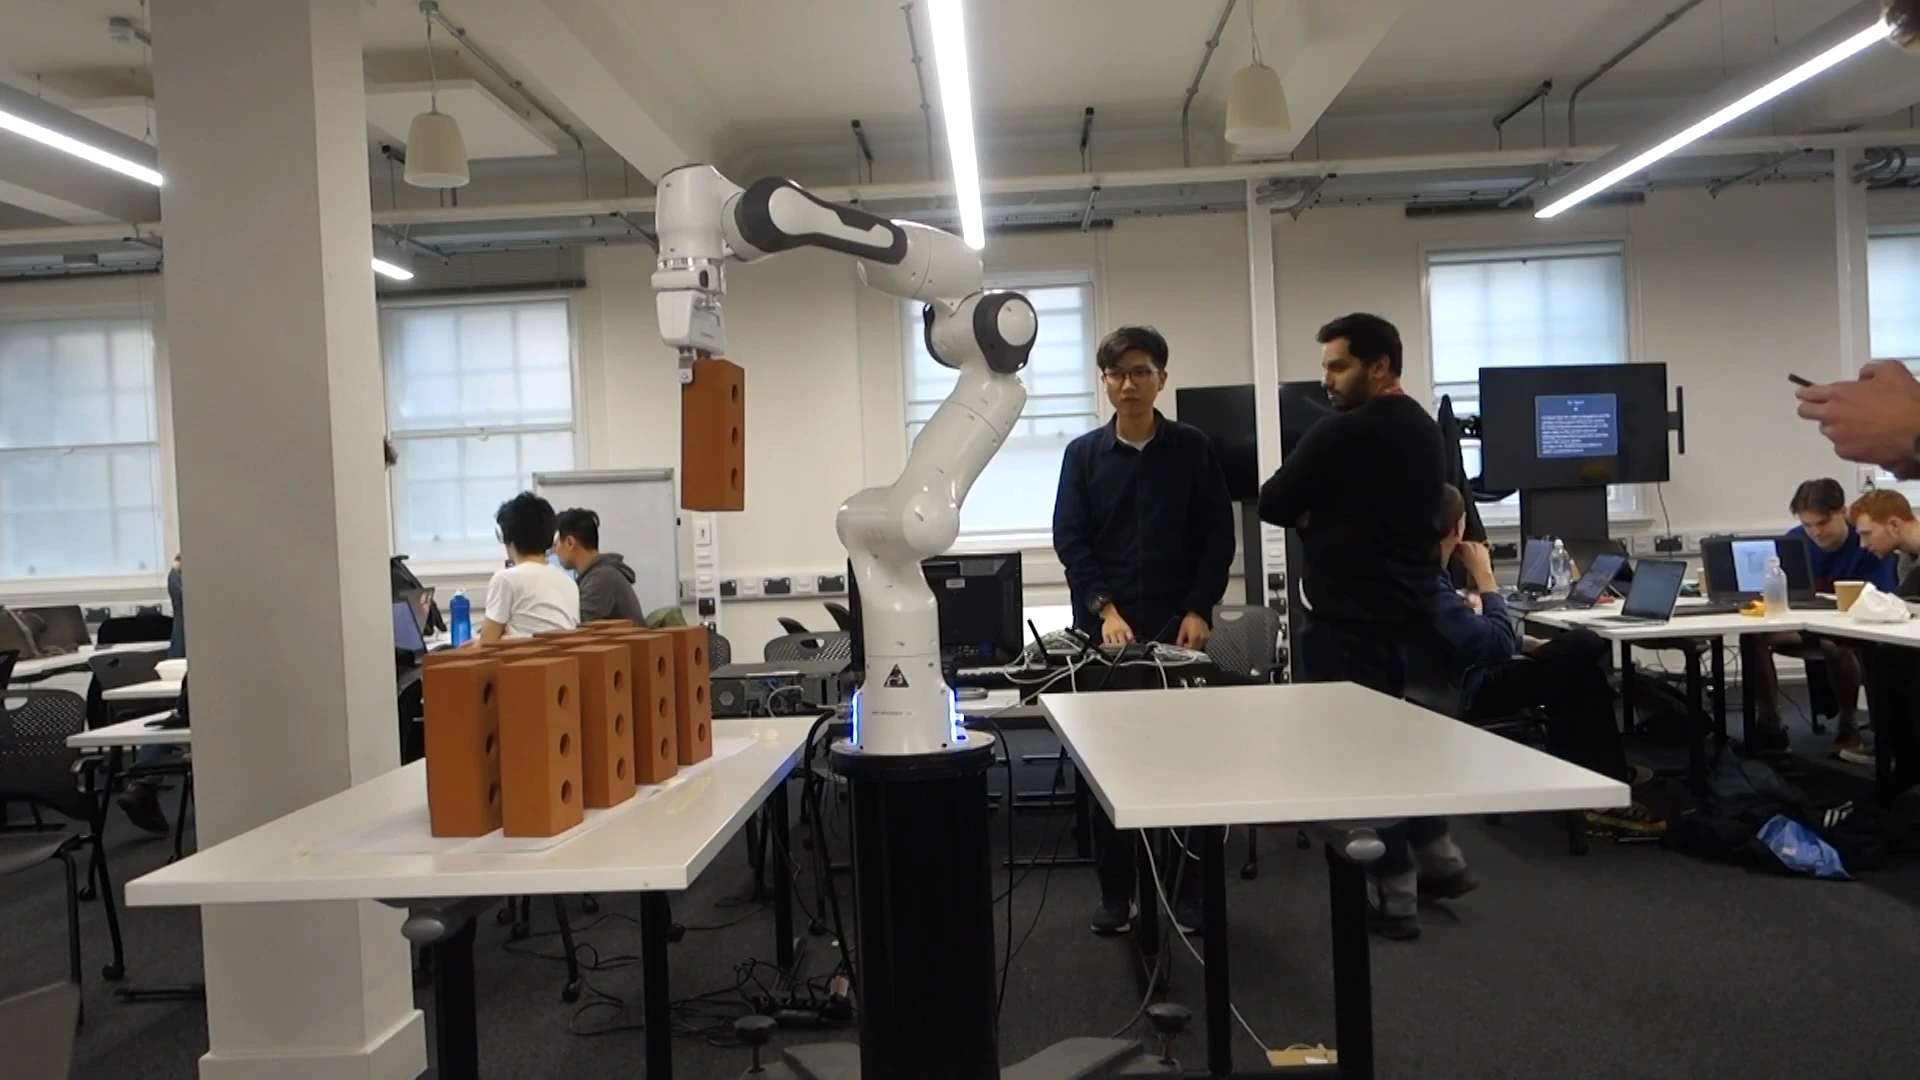
Completed basic physical-arm manipulation and brick-stacking tasks using waypoint-defined motions.
Independent projectRobot operation and waypoint setup